PROJECT 02 / local agent team
JARVIS Local Agent Team on OpenClaw
A boss agent that hands work to Research, Coder and QA agents, all running locally.
- OpenClaw
- Ollama
- qwen2.5:7b
- Discord
Source private: not published
- Type
- AI
- Source
- Private
- Role
- Built and run by me as a personal project.
- Built with
- OpenClaw, Ollama, qwen2.5:7b

01 / Overview
Overview
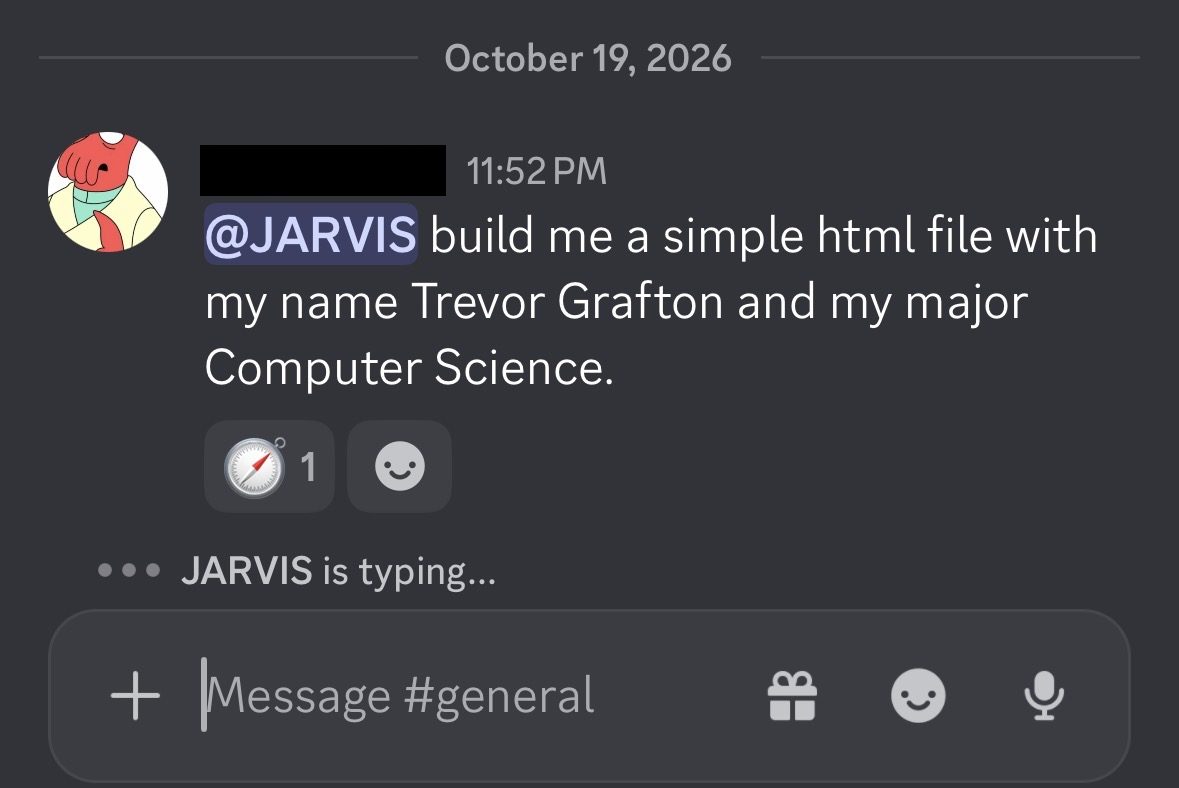
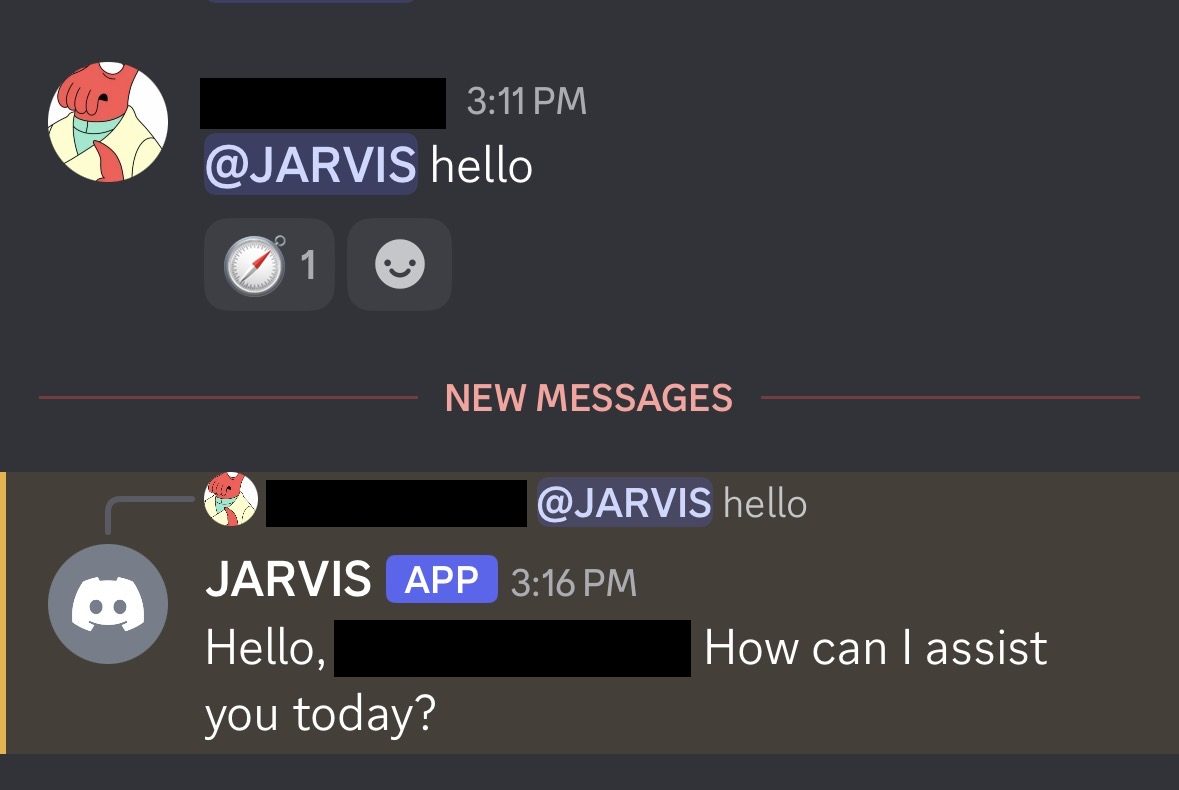
Message JARVIS in Discord
The team is driven through a Discord bot.
JARVIS hands out the work
The boss agent assigns tasks to Research, Coder and QA agents, each with its own room.
A local model answers
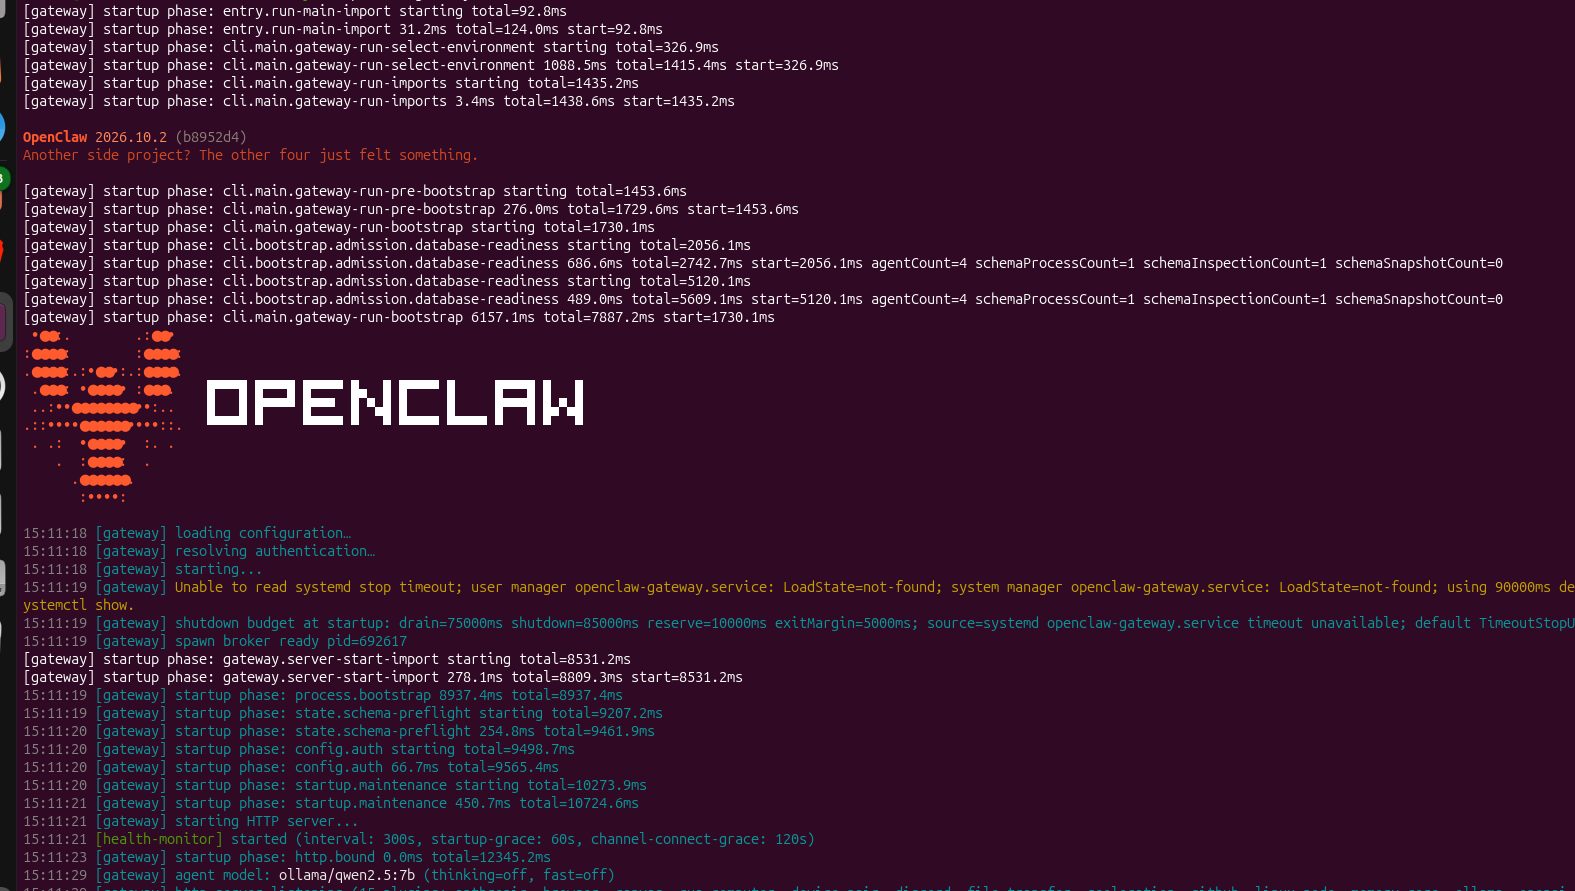
OpenClaw runs the agents on qwen2.5:7b through Ollama, on my homelab.
Watch it move
A live event log shows task_assigned, handoff and file_saved, with an office GUI on top.
02 / Context and problem
Context and problem
This is my own project and everything here is owner-reported from my published posts; no public source is linked and I have no file-backed measurements for it. The model runs locally through Ollama on my homelab. The goal is a backup assistant, not a stand-in for the hosted tools.
03 / My role
My role
Built and run by me as a personal project.
04 / How it works
How it works
- A boss agent (JARVIS) assigns tasks to Research, Coder and QA agents.
- OpenClaw runs the agents on the local ollama/qwen2.5:7b model and is driven through Discord.
- A live event log shows task_assigned, handoff and file_saved as work moves between rooms.
- The gateway is bound to loopback and the bot token lives in an environment variable.
05 / Key decisions
Key decisions
Gateway bound to loopback
Stated in my post; no reason is given there.
Bot token in an environment variable
Stated in my post; no reason is given there.
Discord plugin explicitly trusted
Stated in my post; no reason is given there.
A local model as the backup
The goal in my post is a backup coding assistant when the weekly Claude Code usage runs out.
06 / Results and numbers
Results and numbers
44
tool definitions in the agent prompt
07 / Limitations
Limitations
- Slow on CPU: with 44 tool definitions plus a system prompt and workspace files, a 7B model spends most of its time on prompt processing.
- No latency benchmarks, and no hosted-versus-local comparison yet.
- No public source is linked.
08 / What I learned
What I learned
- Prompt and tool overhead, not the model's answer, dominates local latency.
09 / What's next
What's next
- Profile latency, trim tools and tune context size.
- Benchmark hosted against local.
- Add specialised roles and memory folders backed by Obsidian.
10 / Media gallery
Media gallery
11 / Next project